How much does serpstack cost?
serpstack has a free plan with 100 searches a month for non-commercial use. Paid monthly plans are $29.99 for 5,000 searches, $99.99 for 20,000 and $199.99 for 50,000, which works out to roughly $6, $5 and $4 per 1,000. Annual billing lowers each plan, and enterprise pricing is by quote. If you go past your quota, serpstack bills overage fees rather than cutting you off, and it emails warnings at 75%, 90% and 100%.
Who runs serpstack?
serpstack is built and maintained by APILayer, the company behind a catalog of small developer APIs including currencylayer, ipstack, mediastack and scrapestack. One APILayer account, key and bill covers all of them. That bundling is serpstack's main practical advantage: a team already using scrapestack for page fetching can add Google SERP data without signing up with another vendor.
Which search engines does serpstack support?
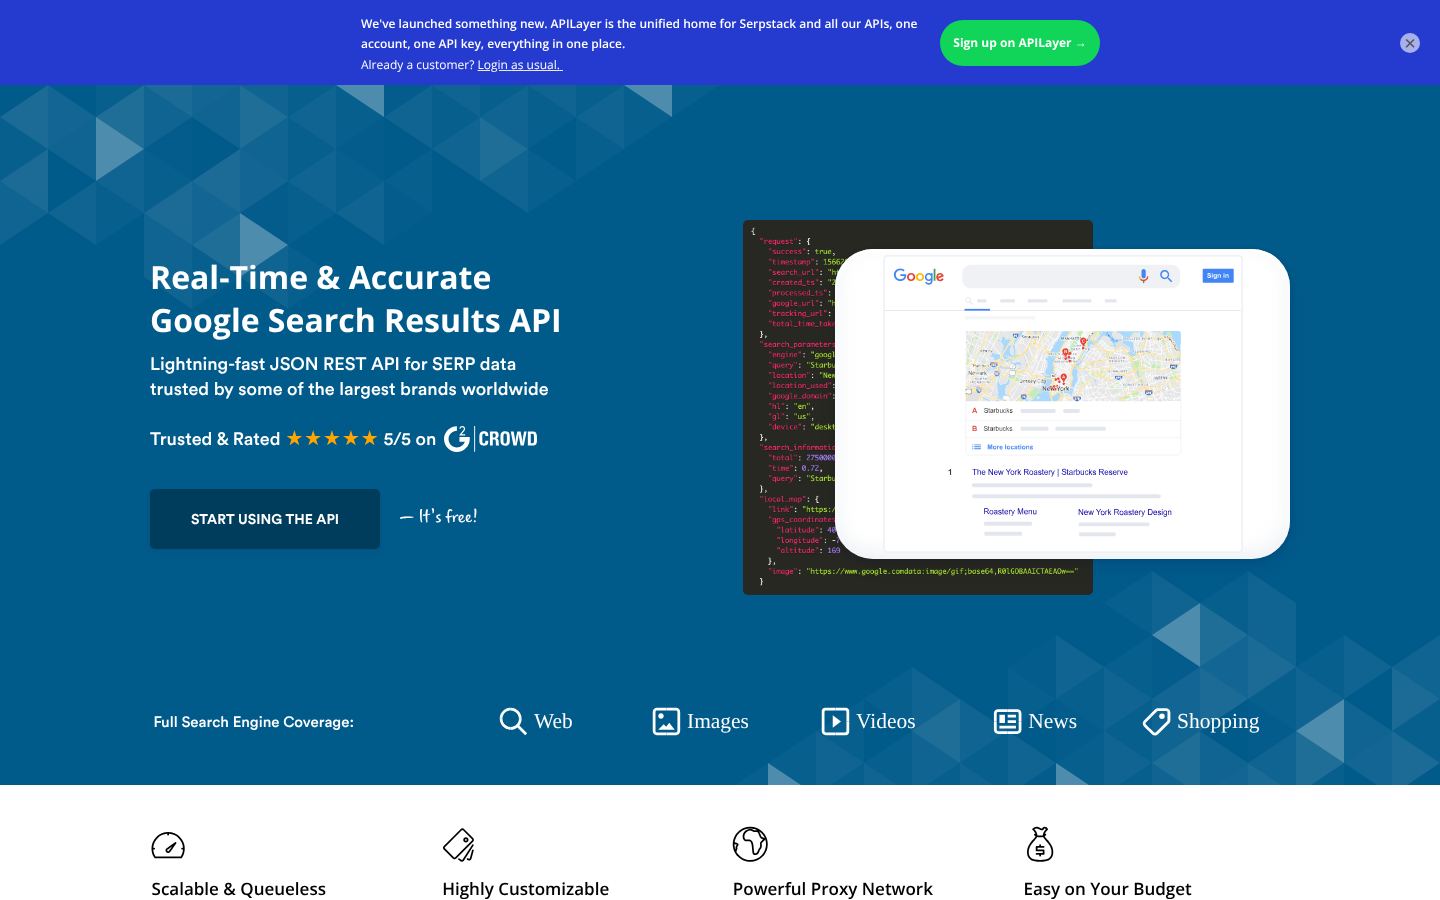
Google only. serpstack says it supports nearly all Google result types, including organic web results, images, videos, news, shopping, sponsored ads and related questions. You can set location, language and device per request. If you need Bing, Yahoo, Baidu or other engines in the same response format, look at a multi-engine provider such as SerpApi or DataForSEO instead.
Is serpstack a good fit for AI agents?
It works, since any agent can call a JSON REST endpoint, but the economics are weak. At $4 to $6 per 1,000 searches on published plans, serpstack costs several times more than pay-as-you-go Google APIs like Serper.dev. An agent that fires several searches per user task will feel that. serpstack also has no MCP server or LLM-specific output, so you would write the tool wrapper yourself.
Is serpstack open source or self-hostable?
No. serpstack is a hosted, proprietary API running on APILayer's cloud infrastructure. It uses a proxy network and APILayer's own scraping and CAPTCHA-handling code to fetch results, and you only see the JSON or CSV it returns. There is nothing to deploy on your own servers. If you need scraping to stay in your own environment, you will have to run an open-source scraper and maintain the Google parsing yourself.